On-call Scheduling Tools: Evaluating Rotation Logic, Escalation Reliability, and Alert Routing
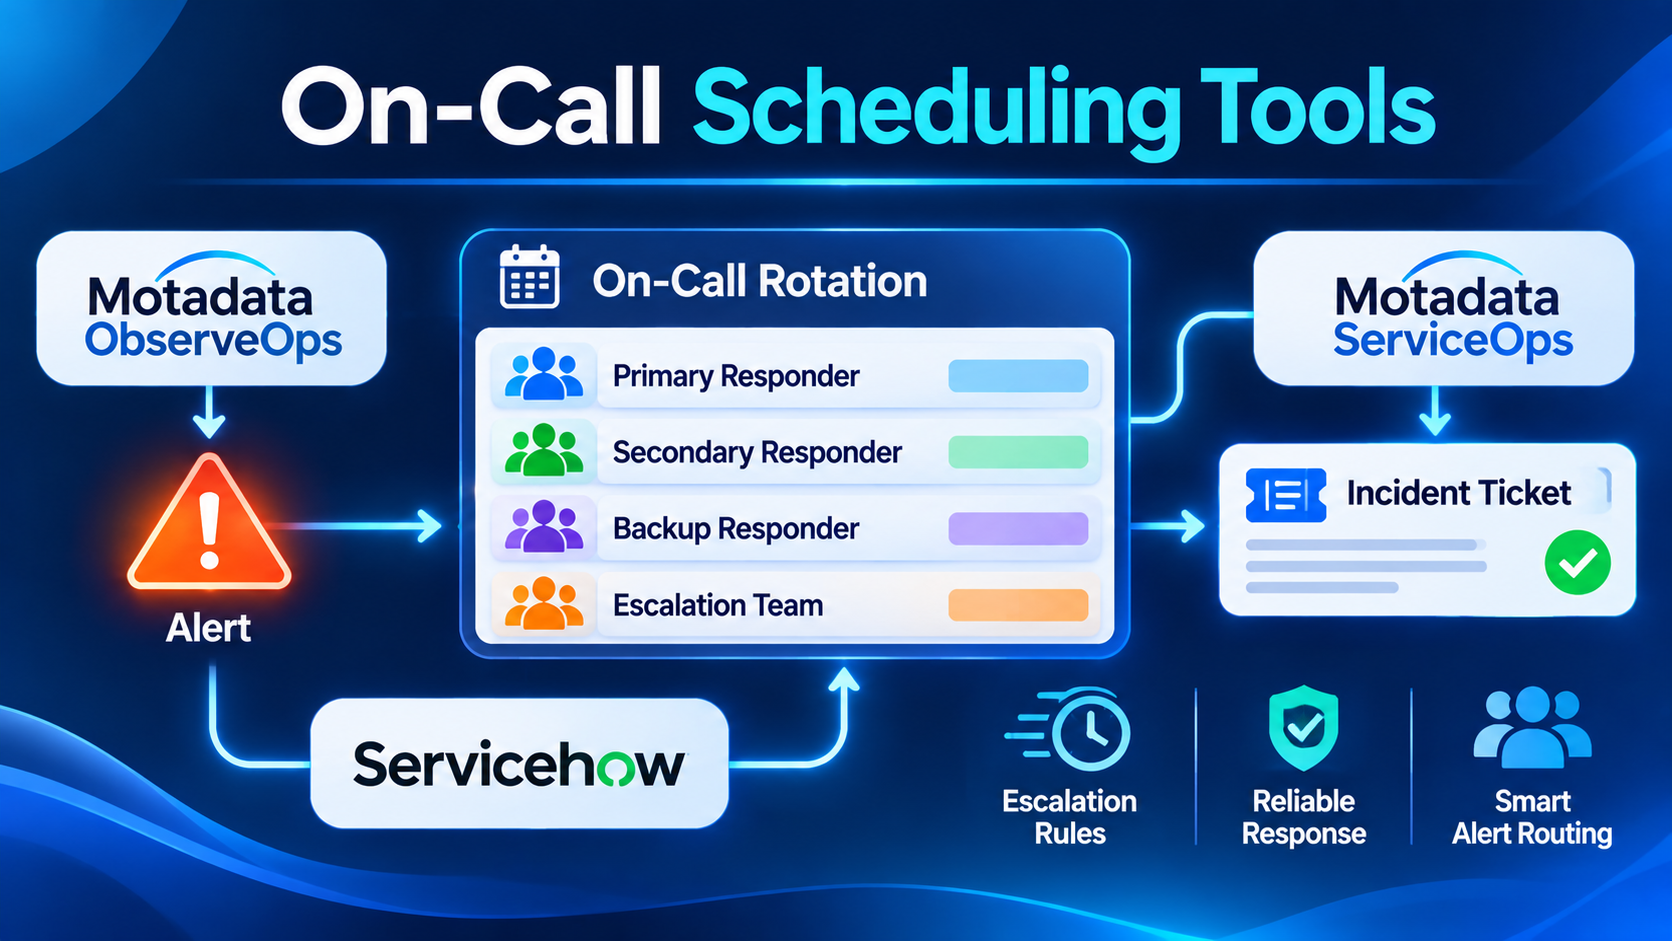
A shared spreadsheet for on-call shifts works fine when three engineers trade weekend coverage on a single service. The moment […]
A shared spreadsheet for on-call shifts works fine when three engineers trade weekend coverage on a single service. The moment […]
When a payment processing service degrades at 3:00 AM, the difference between a five-minute recovery and a two-hour outage rarely […]
Real User Monitoring (RUM) relies on live customer traffic to surface latency and errors—which means when traffic drops overnight or […]
Synthetic Lighthouse audits run on fast fiber connections and clean desktop VMs routinely report green scores while real users on […]
When a single user checkout triggers forty asynchronous calls across API gateways, authentication services, Kafka queues, and database shards, aggregate […]
Centralizing logs from a handful of servers is straightforward; keeping log ingestion affordable and queryable when hundreds of microservices emit […]
A sudden p99 latency spike during checkout rarely announces whether the culprit is an unindexed SQL query, thread-pool starvation in […]
When an API gateway starts returning intermittent 504 timeouts at 2:00 AM, having three separate dashboards—one for Kubernetes CPU metrics, […]
Every engineering team ships code continuously, yet most customers still discover major features by accident—or learn about breaking API changes […]
Compiling a container image in CI takes minutes; getting that release safely through staging, compliance sign-offs, canary traffic shifting, database […]